Open-source uzu runs a 9B LLM about 4x faster than llama.cpp on an M5 MacBook Pro
Avi Chawla (@_avichawla) shared side-by-side numbers in a post with about 670 likes.

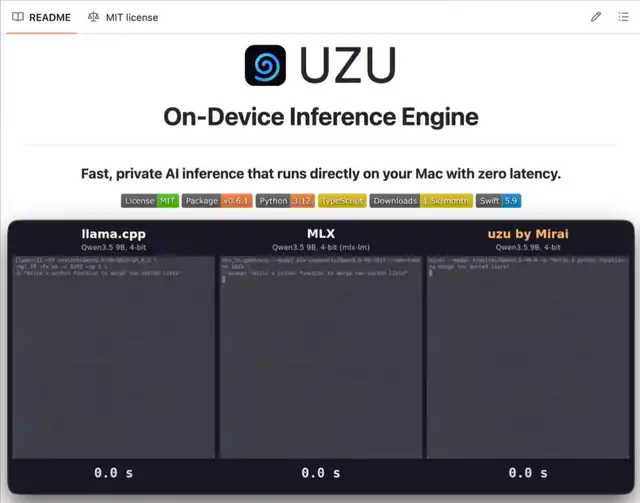
Running Qwen3.5 9B on a base M5 MacBook Pro, Avi Chawla measured 22.0 tokens/s with llama.cpp, 25.1 with MLX, and 92.1 with uzu.
He explains that local decoding is limited by memory bandwidth, about 29 tokens/s for this setup at one token per pass. uzu uses speculative decoding: a small drafter proposes tokens, a tiny adapter builds a tree, and the 9B model verifies it in one pass, averaging about 7.5 tokens per pass.
uzu is an open-source inference engine by Mirai Labs, written in Rust with Metal kernels, with Swift, Python, TypeScript and Rust bindings.